DEEPVIDEO 2.0 BETA · COMING SOON
A Complete Rebuild — A New Era of Video Translation & Dubbing
Tauri 2 + Rust native rebuild · 77× faster startup · 100% offline processing
Release date: October 1, 2026 | Platforms: macOS (Apple Silicon / Intel) · Windows
Summary: DeepVideo 2.0 is a complete rebuild from the ground up. We ditched the old Python + FastAPI architecture in favor of Tauri 2 + Rust to create a truly native desktop app. The change isn’t just numbers on paper — it’s speed and fluidity you can feel every time you open the app and process every video.
- 77× faster startup — navigation + skeleton screen visible within 73ms
- Dramatically lower memory usage — streaming voice separation cuts memory for 45-minute audio from 3.4GB to 70MB
- 100% offline processing — your video data never leaves your computer
- Consistent cross-platform experience — macOS and Windows fully feature-aligned
Brand-New Features
🎓 Expert Video Translation Pro Workflow
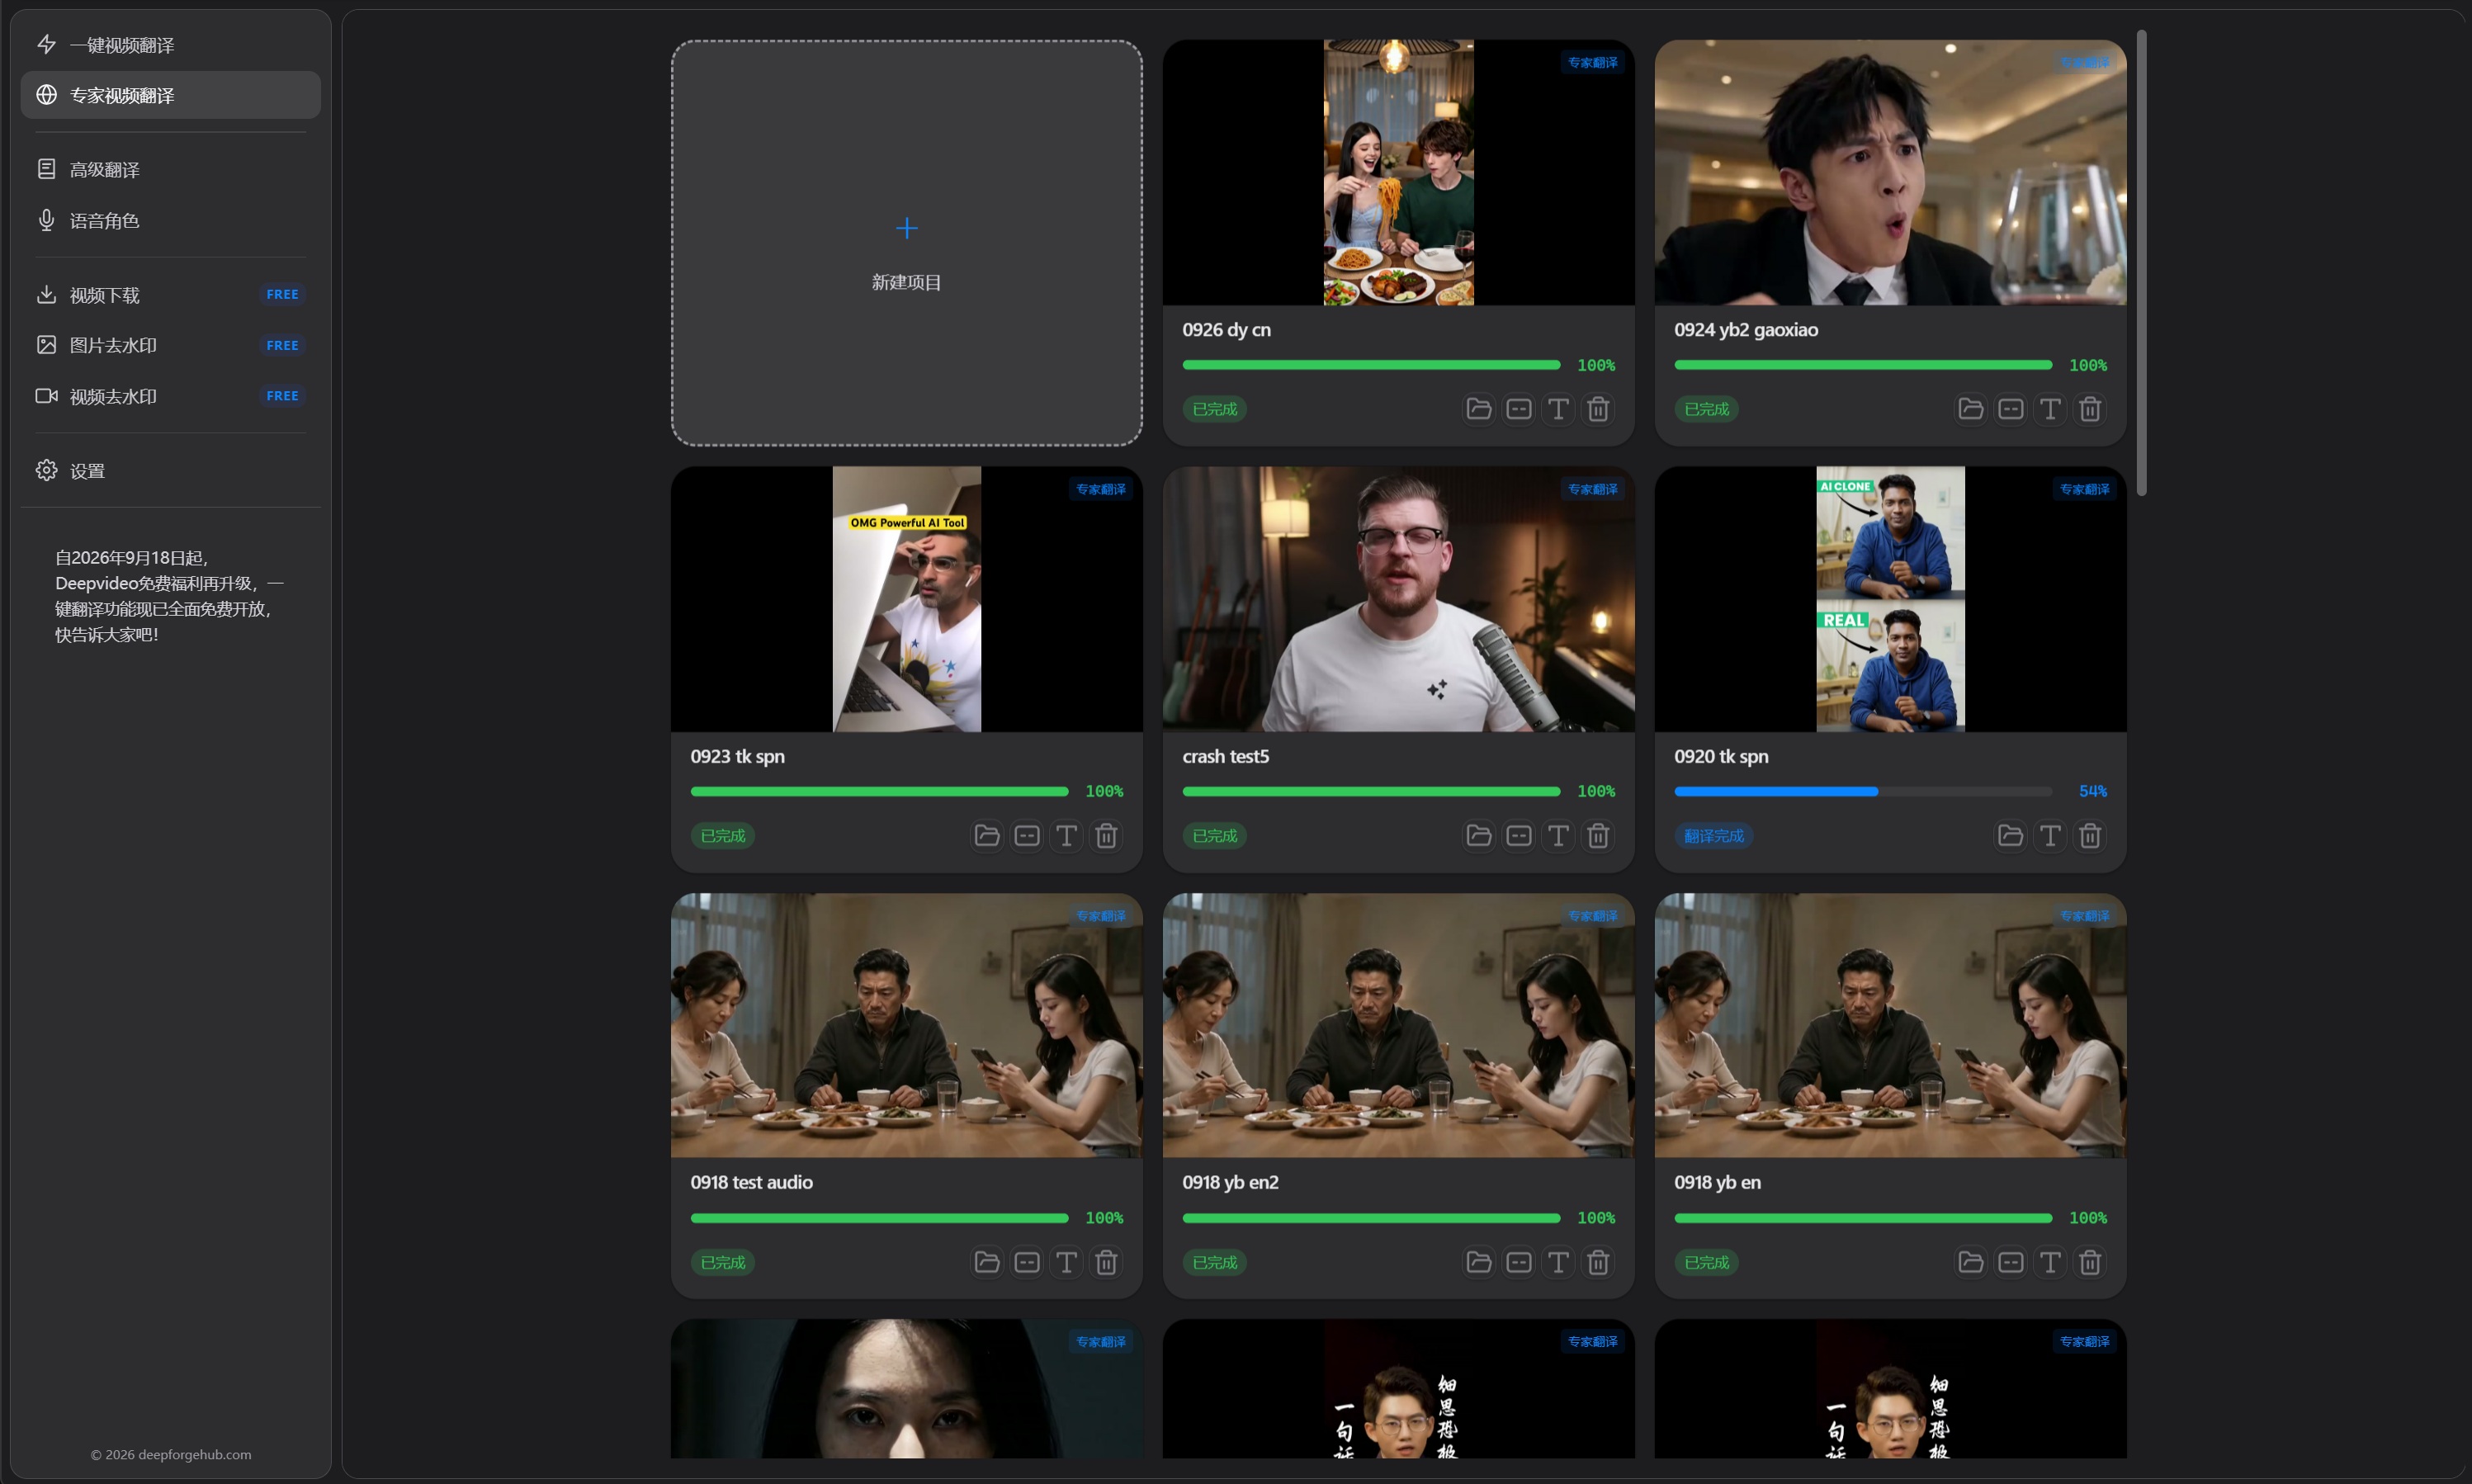
A full-pipeline translation workflow for professional users: a 10-step pipeline with advanced translation options — set translation style, target industry, and glossary; native multi-speaker mode and emotion recognition, plus pause-after-translation review so you can review before synthesis continues.
⬇️ Video Download Free to UseBuilt-in yt-dlp
Built-in yt-dlp tool for one-click downloads from major platforms, with the option to create a translation project right after downloading — download and translation closed-loop in one app, no third-party tools needed. This feature is free to use — no subscription required.
🖼️ Image Watermark Removal Free to UseLaMa Inpainting
AI automatically detects watermark locations and removes them with the LaMa inpainting algorithm, with batch processing support — import many images at once, export in one go. This feature is free to use — no subscription required.
🎬 Video Watermark Removal Free to UseFrame-by-Frame AI Erasing
Smart detection of hardcoded subtitles and watermarks with frame-by-frame AI erasing: the new GrowPolicy reduces accidental damage by 61–87%, validated on a corpus of 10 videos / 118 frames. This feature is free to use — no subscription required.
Core Upgrades
🎙️ SenseVoice Speech Recognition Recognition Engine
The brand-new SenseVoice engine is now live. For casual Chinese speech, noisy environments, phone recordings and more, its recognition accuracy far exceeds Whisper:
- Completely fixes Whisper’s homophone errors — cases like mis-hearing that no bigger model could ever fix are gone for good
- Cantonese support — where Whisper forces Cantonese into Mandarin, SenseVoice outputs authentic Cantonese text
- Smart routing: Chinese, Cantonese and Japanese automatically go to SenseVoice; other languages go to Whisper
- Word-level timestamps for more precise subtitle alignment
🗣️ Chatterbox Voice Cloning
The new Chatterbox voice cloning engine is fully integrated into the production pipeline:
🎶 RoFormer Vocal Separation New Default Engine
RoFormer replaces Demucs as the default vocal separation engine, validated by A/B blind testing on 19 audio clips: RoFormer 14 wins / 4 losses vs Demucs 11 wins / 7 losses.
- Fixes female vocals being cut off and voiceovers being swallowed
- Significantly less residual vocals in background music
- Streaming processing cuts memory for 45-minute audio from 3.4GB to 70MB (48×)
👥 358 System Voice Characters Voice Library
A brand-new system voice library covering 10 languages (Chinese, English, Japanese, Korean, German, French, Spanish, Italian, Portuguese, Russian) and 8 categories (characters, narration, business, education, entertainment, news, stories, animals), with a built-in smart assignment algorithm that matches the most suitable voice based on speaker gender.
⚡ One-Click Translation Minimal Workflow
The brand-new one-click translation mode compresses the entire pipeline into a single step:
- Select a video, click translate
- Automatically: audio extraction → vocal separation → speech recognition → translation → speech synthesis → muxing
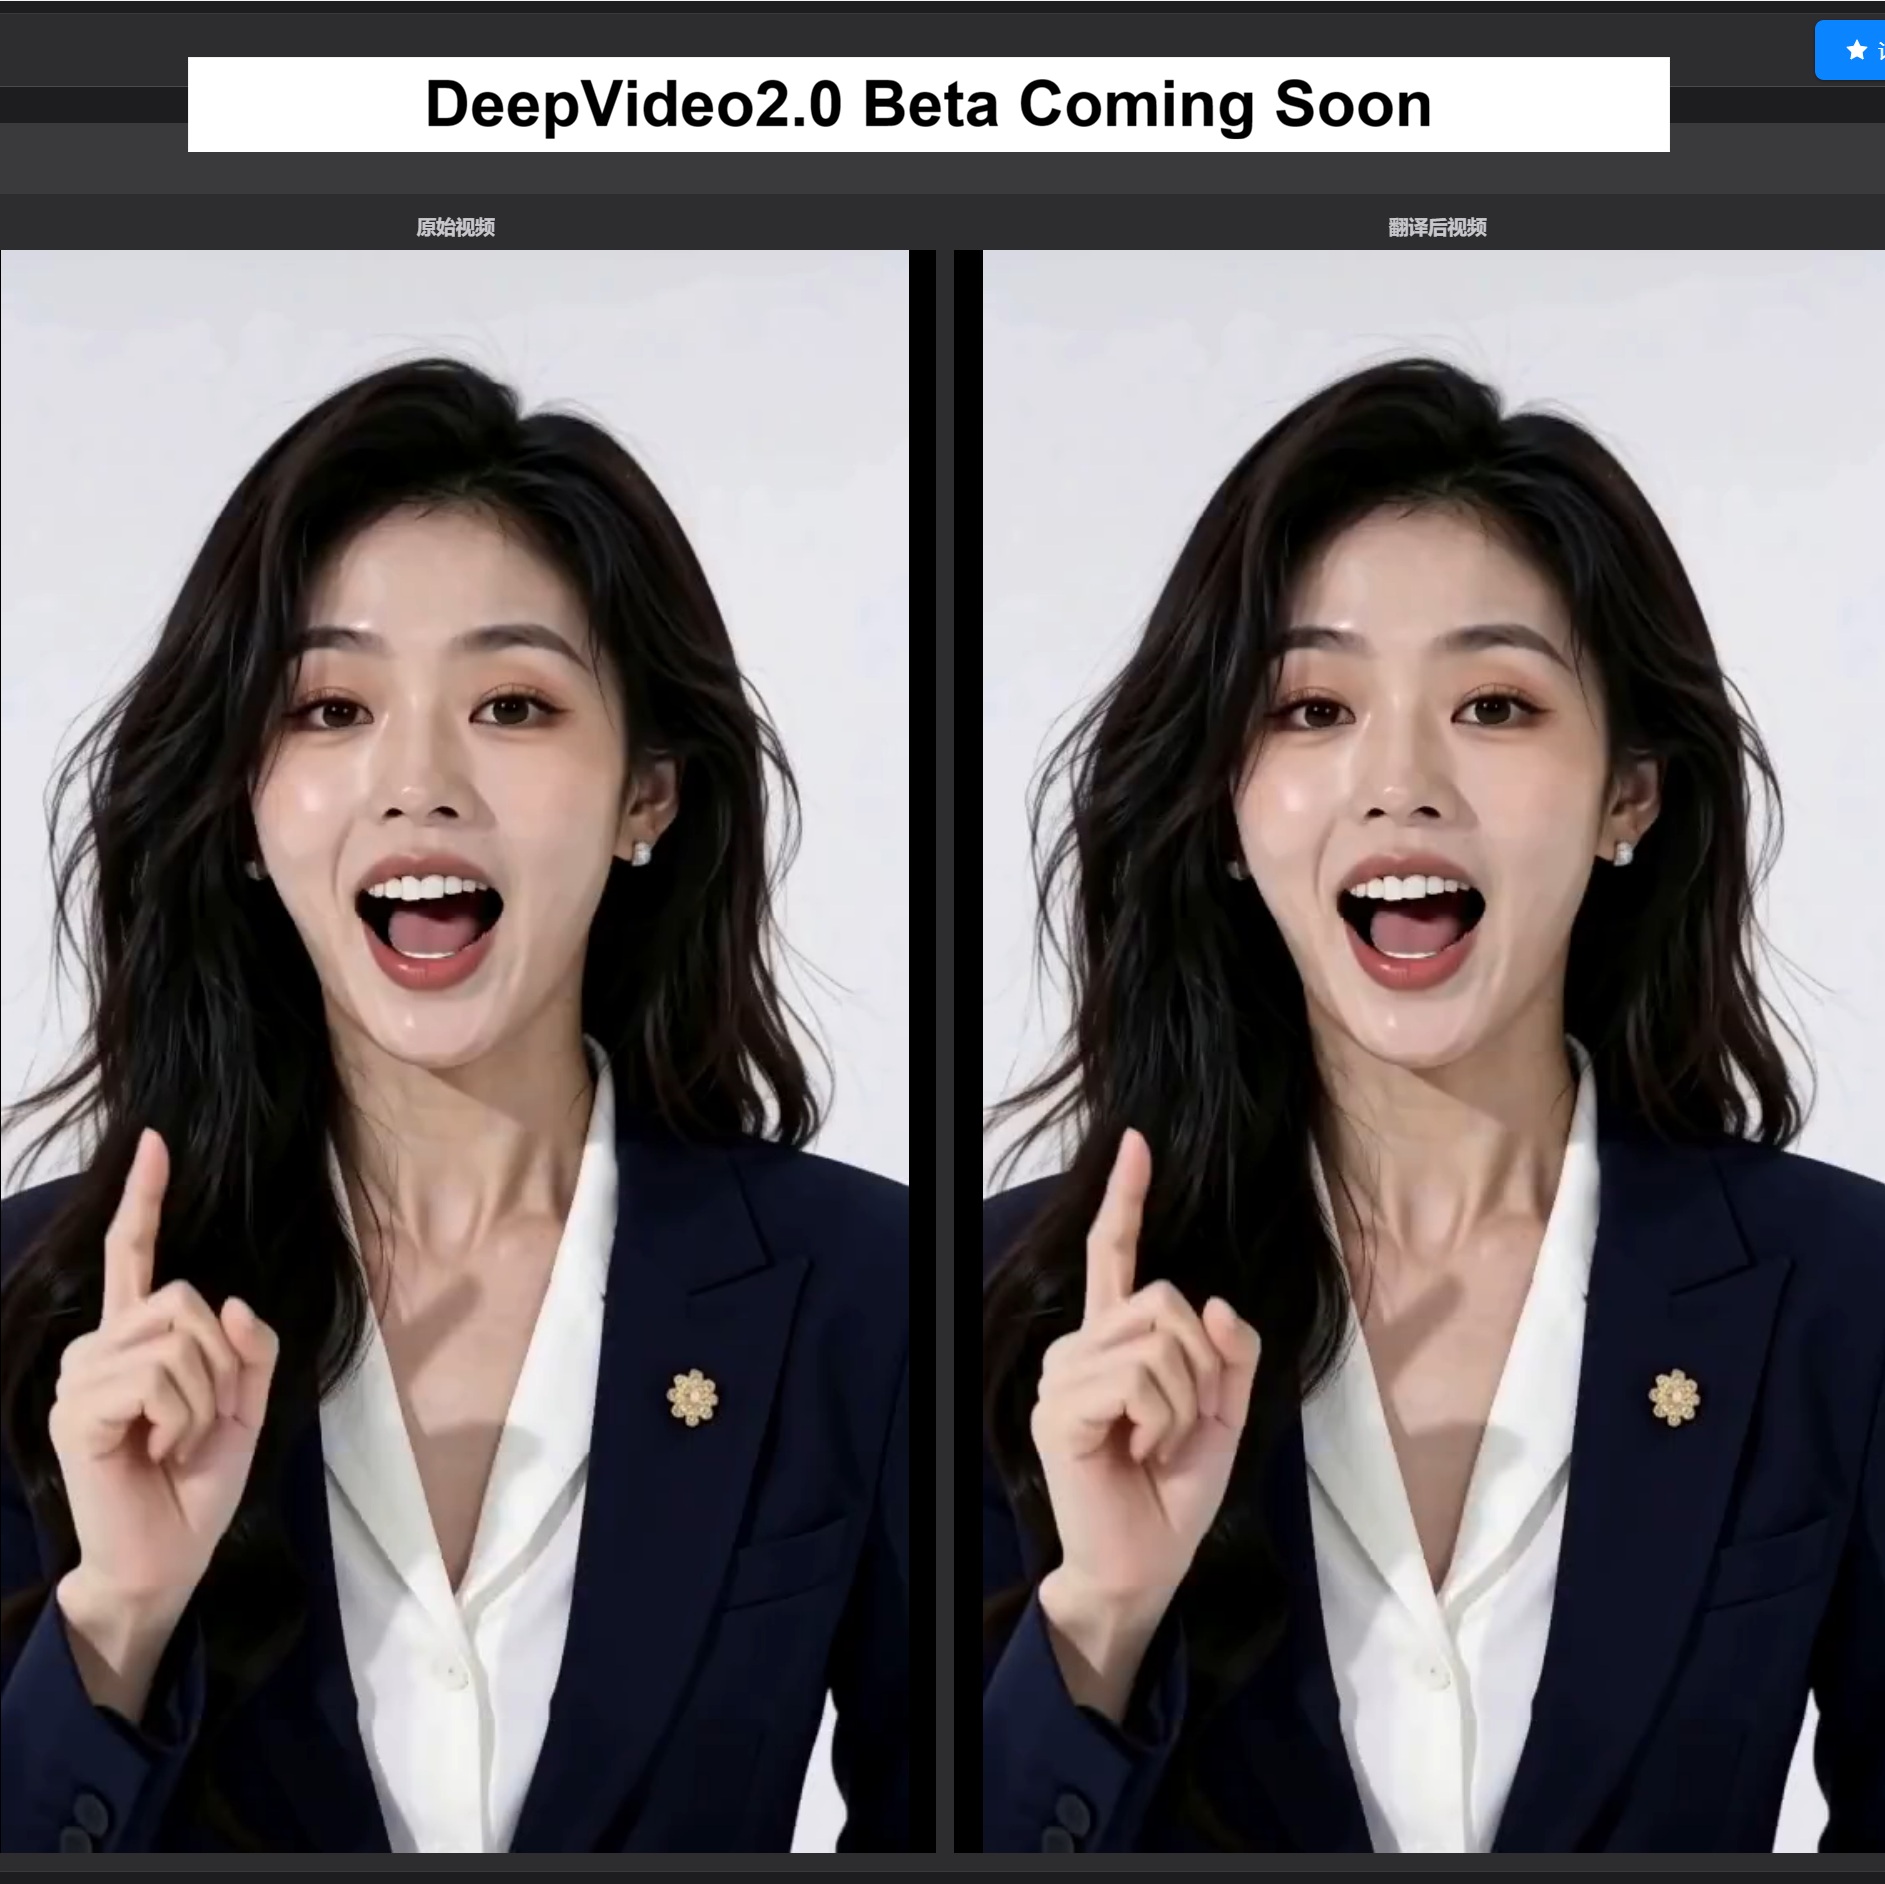
- After translation, go straight to the preview page with original and translated videos side by side
- Need fine-tuning? Jump into the subtitle editor with one click
Want to see what others have created with DeepVideo? Browse the Works showcase; new users can get started with the DeepVideo User Guide.
Experience Improvements
✏️ Editor Upgrades Editor
- Per-segment TTS preview — no need to regenerate the whole audio track; click and listen per segment
- Smart edit journal — only writes back changed settings, never overwrites unmodified ones
- SRT import/export — supports SRT files with speaker info
- LLM source-subtitle correction — automatically fixes speech recognition errors (original_corrected.srt)
- Font size control — adjust subtitle styling in real time
🧽 Hard-Subtitle Removal Improvements Erasing Algorithm
Major improvements to the hard-subtitle erasing algorithm: the new GrowPolicy reduces accidental damage by 61–87%; the mask retention cap leaves no residue after subtitles leave the erasing zone; exit frames no longer freeze the background. Validated on a corpus of 10 videos / 118 frames plus 363-frame end-to-end tests.
👥 Speaker Diarization Improvements Diarization
- Dual-metric merging — weak clusters use group cosine ≥ 0.35, strong clusters use pairwise centroid cosine ≥ 0.45, fixing different speakers being fused together
- Iterative splitting at every speaker boundary, not just the first
- Ignores sub-1-second bursts, eliminating ghost speakers
🍎 Mac App Store in Preparation App Store
DeepVideo 2.0 is being prepared for Mac App Store release: fully sandbox-compatible builds, security-scoped bookmarks persisting file access across restarts, legacy data migration shrunk from ~32GB to ~4MB, and the privacy manifest (PrivacyInfo.xcprivacy) already included.
Performance at a Glance
| Metric | DeepVideo 1.x | DeepVideo 2.0 | Improvement |
|---|---|---|---|
| Startup time | ~5.6s | ~73ms | 77× |
| Vocal separation memory (45min audio) | 3.4 GB | 70 MB | 48× |
| Project list DOM nodes | Full rendering | Paginated, 30 per page | −86% |
| FFmpeg audio loading | 1,432 MB/h | 220 MB/h | 6.5× |
| SenseVoice recognition (196s audio) | — | ~26s (4 threads) | — |
For the full changelog, see the Release Notes.
Supported Languages
UI languages: 20 | Speech recognition: auto-detected, supporting Chinese, Cantonese, English, Japanese, Korean, German, French, Spanish and more | Speech synthesis: 10 languages
Final Words
From 1.0 to 2.0, we did more than swap the tech stack. We rethought how “video translation” should be done — less waiting, lower resource usage, more accurate recognition, more natural voices. Our thanks to every beta tester. If you run into any issues, feel free to contact us. See you on October 1.
Further Reading: DeepForgeHub Research Reports
- Voice Clone Models Compared
- Multi-Speaker Diarization Models Compared
- Subtitle Removal Models Compared
- Video Watermark Removal Tools Compared
- Video Downloader Platforms Compared
- TTS Models Compared
- AI Video Translation Software Pricing Report
- Why DeepVideo Is So Much Cheaper
- Video Translation Software Landscape (18 Tools)
More Research Reports
- Digital Human Models Compared
- Traditional Digital Humans vs Text-to-Video
- Voice Library Models Compared
- Lip-Sync Models Compared
- MiniMax H3 Acceleration & LoRA
- Text-to-Image Models Compared
- Global Text-to-Video Models Report
- Text-to-Video Pricing Report
- Text-to-Video Scene-by-Scene Comparison
See You on October 1
DeepVideo 2.0 Beta launches on October 1, 2026. The Mac App Store version is coming soon.
Download from the Official Site
Free quota: 18 minutes + 2 minutes daily | 100% local processing, never uploaded to the cloud